Data governance before AI governance: Why the order matters
Enterprises rushing to stand up AI governance frameworks are often building the roof before the foundation. AI governance defines how models behave, whether outputs are fair, and how AI risk is monitored. None of that holds up if the data underneath is inconsistent, unowned, and untraceable, because AI governance applies rules to data it assumes is already trustworthy. When AI initiatives stall, the post-mortems rarely blame the algorithm. The failure traces back to the data. That is why the order matters. Data governance establishes the standards, lineage, and ownership that AI governance then applies to AI-specific risks. Skip the first, and the second has nothing solid to stand on. The enterprises scaling AI successfully treat data governance not as a prerequisite to delay action, but as the foundation the whole AI program depends on. Data governance and AI governance are not the same thing The two are often conflated, and that confusion is where the sequencing goes wrong. Data governance is the enterprise-wide rulebook for data assets: quality, ownership, lineage, access, and lifecycle for all data, not just data used for AI. AI governance extends oversight to the models themselves, addressing fairness, transparency, and ongoing risk. The relationship is directional. AI governance cannot succeed without strong data governance, but data governance alone does not address model behavior or AI risk monitoring. Data governance ensures the inputs are trustworthy, and AI governance ensures the outputs are reliable and explainable. Treating them as one function creates blind spots, and building both on a coherent enterprise architecture and data integration foundation is what keeps them aligned. Why data governance has to come first The sequencing is not arbitrary. Even the most sophisticated model produces flawed results when trained on inconsistent or inaccurate data, so governing the model without governing the data solves the wrong problem. Consider what AI governance depends on. Model oversight needs to know what data a model used, whether that data was accurate, who owns it, and whether its use was authorized. Every one of those answers comes from data governance. Without documented lineage, you cannot explain a model’s decision. Without clear ownership, no one is accountable when AI surfaces a data quality issue. Without classification and access control, an AI system touches data it should never reach. Building these foundations through disciplined analytics and reporting, and data management is what makes AI governance enforceable rather than theoretical. What breaks when the order is reversed Enterprises that stand up AI governance on an ungoverned data foundation hit predictable failures, and naming them shows why the sequence is not optional. Model outputs cannot be trusted or explained Without governed lineage and quality, a model’s output has no traceable basis. When a regulator or an executive asks why the AI made a decision, there is no answer, because the data governance that would provide it was never built. The data attack surface expands unchecked As more systems consume data programmatically, the risk of exposure grows. Classification and role-based access, both data governance functions, ensure AI systems only touch data they are authorized to use. Skip them and every new AI use case widens the exposure, which is why access control belongs in the data infrastructure layer beneath AI, not bolted on above it. Accountability has no home Governance without accountability is just documentation. Data governance assigns ownership, naming who is responsible for the accuracy of each data domain. Without that human infrastructure, AI governance has no one to escalate to when something goes wrong. How to sequence the two correctly Getting the order right does not mean finishing all data governance before touching AI governance. The goal is establishing the data foundation first and developing the two in a deliberate sequence. Establish data quality, ownership, lineage, and classification as the foundation Apply access controls so AI systems reach only authorized data Build AI governance on top, defining model behavior, monitoring, and human oversight Develop both in tandem once the data foundation is stable, since they are complementary Frameworks like the NIST AI Risk Management Framework, now being operationalized across US enterprises, assume this trustworthy-data foundation. Grounding the work in a governed work and operations management approach keeps data and AI governance evolving together rather than in conflict. Build the foundation, then govern the AI The enterprises that scale AI responsibly are the ones that resisted the urge to lead with AI governance and built the data foundation first. Data governance is not the boring prerequisite that delays the exciting AI work. Trustworthy inputs, clear ownership, explainable lineage, and controlled access are what make the AI work at all. Reverse the order, and AI governance becomes a set of policies with nothing solid underneath. Get the sequence right, and every AI initiative that follows stands on a foundation that holds. If your organization is building its data and AI governance foundation, connect with Advaiya’s team. Advaiya combines Microsoft data platform and enterprise architecture expertise to establish the data governance foundation- quality, ownership, lineage, and access control- that makes AI governance enforceable and AI initiatives trustworthy. Frequently asked questions What is the difference between data governance and AI governance? Data governance is the enterprise-wide rulebook for all data assets, covering quality, ownership, lineage, access, and lifecycle. AI governance extends oversight to the models themselves, addressing fairness, transparency, and risk monitoring. Data governance ensures inputs are trustworthy; AI governance ensures outputs are reliable and explainable. Why does data governance need to come before AI governance? Even the most sophisticated model produces flawed results on inconsistent or inaccurate data. AI governance depends on knowing what data a model used, whether it was accurate, who owns it, and whether its use was authorized, all of which come from data governance. Without that foundation, AI governance has nothing solid to apply to. Can you do AI governance without data governance? No. AI governance cannot succeed without strong data governance. Without documented lineage, you cannot explain a model’s decision; without clear ownership, no one is accountable for data
Is your data infrastructure actually ready for agentic AI? A readiness checklist
The reason most agentic AI projects stall is not the model. The problem is the data underneath it. An agent that reasons and acts autonomously is only as reliable as the data it draws on, and most enterprises have more data than they can vouch for: fragmented across systems, inconsistently governed, and missing the context an agent needs to act correctly. Gartner has projected that a majority of AI projects lacking AI-ready data will be abandoned, and data readiness is the factor that surfaces the problem latest and most expensively. The checklist below gives data and platform leaders a structured way to assess whether their infrastructure can actually support autonomous agents before deploying one. The focus is data lifecycle readiness, not model selection, because that is where agent projects succeed or fail. Work through each dimension honestly. The gaps you find now are far cheaper to close than the ones an agent surfaces in production. Why data readiness decides agentic AI success Agents raise the stakes on data quality because they act on it, not just report it. A dashboard with a data error shows a wrong number. An agent with the same error takes a wrong action, autonomously, at machine speed. The dependency is total. Models, agents, and retrieval workflows all draw on enterprise data, and before that data reaches an agent, teams need to know where it originates, whether it meets quality expectations, what context enriches it, who can access it, and how it changes over time. According to Gartner research, a large share of agentic AI projects will be cancelled by 2027, with inadequate data foundations among the leading causes. Closing that gap depends on the enterprise architecture and data integration that makes data trustworthy before an agent acts on it. The data readiness checklist Assess each dimension below. Readiness is not all-or-nothing, but weakness in any one area caps how much autonomy an agent can safely be given. Data quality and consistency Poor data quality does not just affect reporting, it directly shapes the decisions an agent makes. Confirm that data is accurate, complete, and consistent across sources, and that a process exists for regular quality audits rather than one-time cleanup. An agent should only operate on data the organization trusts enough to act on without a human checking each result. Data context and meaning Data without context is hard for an agent to interpret correctly. An agent might see 250 conversions, but without knowing what counts as a conversion, which business unit it belongs to, and how success is measured, the number is nearly useless. Confirm that business context, definitions, and metadata travel with the data, supported by the analytics and reporting layer that gives numbers meaning. Access control and governance As agents gain autonomy, controlling what they can reach becomes critical. Confirm that a data governance policy exists, sensitivity labels are applied, data owners are named, and agents can only access the information necessary for their specific purpose. An agent should operate within defined governance boundaries, not with broad standing access to everything. Data lineage and traceability Confirm that you can trace where a piece of data originated, how it was transformed, and where it ended up. Lineage is what lets you answer, after an agent acts, exactly what data drove the decision. Without it, debugging an agent’s behavior and satisfying an audit both become nearly impossible. Infrastructure and pipeline scalability Confirm that pipelines deliver the right data at the right time, every time, and scale to the volume and velocity agents demand, including burst scenarios where many agents operate at once. Autonomous workflows place different demands on infrastructure than periodic reporting, which is where a modern data infrastructure foundation matters. How to use the results The point of the checklist is not a pass or fail grade. The goal is matching the autonomy you grant an agent to the readiness you actually have. Weakness in any dimension does not block agentic AI entirely, but it does bound what is safe. An agent can run on data you trust in a well-governed domain even if other areas lag, which argues for starting where readiness is highest rather than waiting for enterprise-wide perfection. Building readiness into existing data quality and platform reviews, and revisiting it when sources or use cases change, keeps the foundation current as the work and operations management around it evolves. Data readiness is not a one-time launch task. Fix the foundation before you deploy the agent Agentic AI does not forgive a weak data foundation, it amplifies it. Every gap in quality, context, access control, lineage, or scalability becomes an autonomous action taken on flawed information. The enterprises deploying agents successfully are the ones that assessed their data honestly first, closed the critical gaps, and matched agent autonomy to the readiness they actually had. The ones that skipped the assessment are discovering their data problems the hard way, in production, at machine speed. If your organization wants to assess and strengthen its data foundation for agentic AI, connect with Advaiya’s team. Advaiya combines Microsoft Azure, data platform, and enterprise architecture expertise to turn fragmented data into the governed, high-quality, well-documented foundation that autonomous agents require. Frequently asked questions What does data readiness for agentic AI mean? Data readiness for agentic AI means your data infrastructure can reliably support autonomous agents across quality, context, access control, lineage, and scalability. Because agents act on data rather than just reporting it, readiness determines whether an agent takes correct autonomous actions or amplifies existing data problems at machine speed. Why do agentic AI projects fail on data? Agents act on data autonomously, so any error becomes a wrong action rather than a wrong number. Fragmented, inconsistent, or ungoverned data directly shapes agent decisions. Gartner projects a large share of agentic AI projects will be cancelled by 2027, with inadequate data foundations among the leading causes. What should a data readiness checklist cover? A data readiness checklist should cover data quality and consistency, data context
Agentic AI and US data privacy rules: what to settle before agents touch your systems
The data privacy frameworks most US enterprises rely on were built for human-speed data access, with penalties calculated per record and per violation. An AI agent that touches thousands of records autonomously in seconds does not fit that model, and regulators have started treating the mismatch as the enterprise’s problem, not the technology’s. Deploying an under-governed agent is increasingly read as intentional conduct, which changes the penalty math entirely. That is the shift leaders need to settle before an agent goes near production data, not after. Agentic AI’s capacity to plan, execute, and adapt a series of actions with minimal human intervention triggers data-access and oversight obligations that generative AI never did. The questions of lawful basis, access scope, auditability, and human oversight have to be answered at design time, because retrofitting them after an incident is where the real cost lands. Why agentic AI breaks the assumptions behind US privacy rules The core problem is speed and scale. GDPR, CCPA, HIPAA, and GLBA were designed around human-paced data handling, and an autonomous agent operating at machine speed multiplies the exposure on every dimension those rules measure. The penalty structures make this concrete. Under analysis from UC Berkeley Law, agentic AI’s ability to independently plan and execute actions generates heightened data-access and human-oversight obligations that distinguish it from earlier AI. When an agent touches personal data across many records, per-record penalties scale with it. Getting ahead of this requires the enterprise architecture and data integration that controls what an agent can reach before it reaches anything. What actually changes when an agent accesses regulated data Several specific shifts turn a manageable compliance posture into real exposure once an autonomous agent is involved. Penalties can move from unintentional to intentional tiers Regulators are beginning to treat the deployment of an under-governed AI agent as de facto intentional conduct. Under CCPA, that shift moves incidents from the lower unintentional penalty tier to the higher intentional tier, and the multiplier applies to every record the agent touched. The distinction between an accident and a choice now hinges on whether governance was in place before deployment. Multi-state deployment multiplies exposure As of early 2026, a large and growing number of US states have enacted their own privacy laws. A single agent deployed across states can trigger concurrent enforcement from multiple state attorneys general, so an agent that works fine in one jurisdiction can create layered liability the moment it operates across state lines. Managing this depends on the data infrastructure that tracks where data lives and which rules apply. Lawful basis has to map to every action A common regulatory finding is no documented legal basis for the specific processing an agent performed, even when a broader basis existed for the underlying data. Each data retrieval an agent makes needs to map to a specific lawful ground, which means the governance has to live at the point where the agent assembles context, not just at the database. What to settle before deployment Enterprises staying ahead of enforcement answer a specific set of questions before an agent touches production data. Which data can each agent access, and is that scope enforced technically rather than by policy alone Is there a documented lawful basis mapped to each type of processing the agent performs Can you produce a decision trace showing exactly what data an agent touched, why, and how you would erase it? Where does human oversight sit for actions that materially influence decisions about individuals? How is agent behavior monitored for drift away from its authorized purpose Treating classification, lineage, and decision traces as compliance infrastructure rather than governance overhead bolted on later is what turns a privacy policy into the ability to show a regulator exactly what an agent did. Building this into business process automation from the start is far cheaper than reconstructing it under investigation. Governance is the deployment gate, not the paperwork Agentic AI does not get a compliance pass for being new. The frameworks apply, the penalties scale with the agent’s reach, and regulators are treating weak governance as an aggravating factor rather than a mitigating one. US enterprises that settle data access, lawful basis, auditability, and human oversight before an agent touches production data deploy with confidence, often grounding the work in a governed AI strategy and infrastructure approach. Those that treat compliance as something to sort out after launch are building the exposure that will define enforcement actions. The governance is not the obstacle to deployment. Governance is what makes deployment safe. If your organization is preparing to deploy AI agents against regulated data, connect with Advaiya’s team. Advaiya brings the enterprise architecture, data governance, and Microsoft security expertise to build the access controls, lawful-basis mapping, and audit traces that let AI agents operate on sensitive data without creating regulatory exposure. Frequently asked questions How do US data privacy rules apply to AI agents? GDPR, CCPA, HIPAA, and GLBA apply fully to AI agents processing personal data, but they were designed for human-speed access. An autonomous agent touching many records at machine speed multiplies exposure on every dimension these rules measure, and regulators increasingly treat under-governed agent deployment as intentional conduct. Why does agentic AI create more compliance risk than generative AI? Agentic AI can independently plan, execute, and adapt a series of actions with minimal human intervention, generating heightened data-access and human-oversight obligations. Unlike generative AI, an agent takes autonomous actions against real data, so each action must have a documented lawful basis and traceable oversight. Can deploying an AI agent increase privacy penalties? Yes. Regulators are beginning to treat under-governed agent deployment as de facto intentional conduct. Under CCPA, that shifts incidents from the lower unintentional penalty tier to the higher intentional tier, with the penalty applying to every record the agent touched, substantially increasing exposure. What should enterprises settle before deploying AI agents? Before deployment, settle which data each agent can access with technical enforcement, a documented lawful basis mapped to each type of
Project Online retirement for infrastructure and construction portfolios: What changes
Project Online retires on September 30, 2026, and for construction and infrastructure teams, the exposure is larger than a tool swap. Over a decade, Project Online became the system of record for cost-loaded master schedules, contractual reporting, subcontractor coordination, and portfolio governance, the exact project controls that keep bids accurate and capital programs on budget. Lose those controls without a plan, and the estimating and allocation errors PMOs spent years eliminating come straight back. The generic migration advice treats this as a like-for-like tool swap. For capital-intensive portfolios, the harder question is which controls survive the move and which quietly break. What is happening to Microsoft Project Online? Microsoft Project Online retires on September 30, 2026. After that date, Project Web App (PWA) sites and the data inside them will no longer be accessible. The timeline has firm markers. According to Microsoft’s official lifecycle documentation, Project Online retires on September 30, 2026, after which the service and its data will no longer be accessible. Sales of Project Online-only plans to new customers ended October 1, 2025, and existing customers cannot create new PWA sites as of April 1, 2026. Microsoft is redirecting investment toward Planner and Copilot-based work management, citing the legacy SharePoint architecture that Project Online was built on. For construction teams, the key point is that Planner is not a like-for-like replacement, and the parts of your process that depend on Project Online may extend well beyond scheduling. Why construction portfolios face a bigger transition than most Construction and infrastructure portfolios carry requirements that general project management rarely touches. That is why a migration plan written for a marketing PMO does not fit a capital program. Consider what Project Online typically anchors in a construction organization. The platform holds cost-loaded schedules where budget and timeline are linked at the task level, supports contractual reporting that owners and regulators require, manages complex resource structures spanning employees, contractors, and subcontractors, and often underpins formal change control, progress measurement, and portfolio governance. Rebuilding these on a new platform requires the enterprise architecture and data integration discipline that connects scheduling, cost, and reporting into one coherent system. What actually changes for capital project teams The retirement touches several areas that construction portfolios depend on, and each one needs deliberate attention. Master schedules and cost-loaded plans Project Online could manage massive schedules with thousands of tasks, deep work breakdown structures, and multi-level dependencies. Lightweight replacements are built for task coordination, not this scale. Capital programs that lose cost-loaded scheduling fall back to spreadsheets, and the estimating and allocation errors that PMOs worked years to eliminate come right back. Contractual and regulatory reporting Infrastructure portfolios frequently feed funding decisions and regulatory reporting from Project Online data. Any replacement has to preserve the reporting structures that owners, auditors, and regulators expect, or the organization risks compliance gaps during the transition. Connecting project data to analytics and reporting that matches contractual formats is essential, not optional. Subcontractor and resource coordination Project Online could automatically rebalance schedules when resources were overallocated. Without that capability, resource managers revert to manual coordination across crews and subcontractors, exactly the fragmentation that portfolio-level resource capacity planning exists to prevent. Historical project data and sharepoint content Construction Project Online environments often connect to SharePoint project sites, document workflows, and approval chains. After retirement, PWA data will not be accessible, so historical schedules, bid records, and project documentation must be exported and preserved before the deadline using disciplined data migration practices. How construction and infrastructure teams should plan the move Large capital organizations rarely have the luxury of a single big-bang change. A phased approach lowers delivery risk and lets the PMO show incremental wins ahead of the deadline. Start by stabilizing the critical portfolios first: the regulatory, board-visible, and revenue-critical programs that carry the most exposure. Move those into the new platform before anything else. Next, optimize by redesigning intake, governance, resource, and financial processes rather than simply replicating old workflows. Rationalize the custom reports and workflows that accumulated over a decade. Finally, scale the model across business units and integrate the new platform with ERP, financial, and asset management systems so project data flows consistently. Treating the retirement as a chance to modernize the operating model, not just the tool, is where forward-looking construction PMOs find real value in work and operations management. Turn a forced deadline into a stronger project controls foundation The Project Online retirement is a hard deadline, but for construction and infrastructure teams it is also a rare opportunity to rebuild project controls on a modern foundation. Handled early and deliberately, this transition protects your master schedules, preserves your historical data, and strengthens the cost and governance controls that keep capital programs on budget. Handled late, it becomes a scramble to save data before access disappears. If your construction or infrastructure organization is planning its move off Project Online, connect with Advaiya’s project services team. With deep experience in construction, EPC, and infrastructure alongside OnePlan and Microsoft expertise, Advaiya helps capital-intensive teams preserve their project data and rebuild the project controls that complex portfolios depend on. Frequently asked questions When does Microsoft Project Online retire? Microsoft Project Online retires on September 30, 2026. After that date, Project Web App sites and the data stored in them become inaccessible. Sales to new customers ended October 1, 2025, and existing customers cannot create new PWA sites as of April 1, 2026. Why is the Project Online retirement a bigger deal for construction firms? Construction and infrastructure portfolios rely on cost-loaded schedules, contractual reporting, subcontractor coordination, and formal change control that lightweight replacements cannot support. Project Online often anchors portfolio governance, funding decisions, and regulatory reporting, so its retirement affects far more than scheduling. Is Microsoft Planner a good replacement for construction portfolios? Planner is built for lightweight task coordination, not portfolio governance, cost-loaded scheduling, or contractual reporting. Construction teams managing capital programs typically need deeper project controls than Planner provides, which is why many evaluate purpose-built PPM platforms
Agentic AI in US manufacturing: The labor shortage angle nobody’s talking about
The agentic AI conversation in US manufacturing is dominated by efficiency and cost, and it is missing the more urgent story. The pressing constraint facing US manufacturers in 2026 is not technology; it is labor. Nearly 500,000 manufacturing jobs sit unfilled because modern factories need digital, robotics, and AI skills the current training pipeline cannot supply at scale, and the gap is widening as baby boomers retire and reshoring accelerates. That reframes what agentic AI is actually for. The point is not primarily to cut headcount in a tight labor market where there is no headcount to cut. The real value is extending the reach of the skilled workers a manufacturer already has, letting a scarce workforce cover more ground. Seen through the labor lens, agentic AI stops being a nice-to-have efficiency play and becomes a workforce strategy. Why the labor shortage changes the agentic AI calculation The US manufacturing labor shortage is structural, not cyclical, which means it will not resolve on its own as the economy shifts. The workforce skews older than the national average, replacement demand is rising, and skill availability rather than raw headcount is now the dominant constraint. The numbers make the pressure concrete. More than 2 million manufacturing jobs could go unfilled by 2028, and the top executive concern is not hiring bodies but equipping workers with the skills to operate smart manufacturing. Agentic AI matters here because it addresses the skills dimension directly, encoding expertise into systems that help a smaller team operate at the level of a larger one. Making that work depends on the enterprise architecture and data integration that connects agents to the systems where skilled work happens. Where agentic AI extends a scarce workforce The most valuable agentic AI deployments in a labor-constrained plant are the ones that let existing workers do more, not the ones that promise to remove them. Capturing and scaling expert knowledge When an experienced operator retires, decades of judgment can walk out the door. Agentic systems that encode best-practice processes into repeatable workflows help preserve that expertise and apply it consistently, so a shrinking pool of experts covers more of the operation. Building this on solid business process automation is what turns individual knowledge into a scalable asset. Handling the coordination work that consumes skilled time Skilled workers spend too much of their day on coordination: chasing status, reconciling systems, and manual replanning. Agents that handle order-to-cash steps, inventory synchronization, and production coordination free those workers for the judgment-intensive tasks only people can do, connecting through the work and operations management systems teams already run. Continuous monitoring a lean team cannot sustain A lean maintenance or quality team cannot watch everything at once. Agentic systems that monitor equipment health, quality signals, and process deviations around the clock extend the reach of a small team, flagging what needs human attention rather than requiring constant human watching. Augmentation, not replacement: what the research actually says The framing that matters most here is augmentation, and the data supports it directly. According to Deloitte’s 2026 Manufacturing Industry Outlook, more than 81% of task hours in manufacturing are expected to remain human-driven, with AI augmenting rather than replacing human talent. That is the correct mental model for a labor-short environment. The uniquely human skills- creativity, collaboration, critical thinking, and adaptability- remain essential, and agentic AI works best fostering a culture where technology augments people. The People-Process-Technology principle applies directly to the labor crisis: technology handles scale and consistency, people handle judgment, and the combination lets a constrained workforce do more. How to approach agentic AI as a workforce strategy Manufacturers that treat agentic AI as a labor strategy rather than a cost-cutting tool make different, better decisions about where to deploy it. Target the workflows where skilled-worker time is most wasted on coordination and manual reconciliation Prioritize capturing expert knowledge before more of it retires out of the building Deploy continuous monitoring where a lean team cannot maintain constant coverage Frame every deployment as extending your existing workforce, which also eases the adoption resistance that kills labor-framed automation Deloitte’s “build, buy, or borrow” workforce framework pairs naturally with this approach, and grounding it in AI strategy and infrastructure built for augmentation is what turns the labor shortage from a pure constraint into a reason to move. Treat the labor gap as the reason to act US manufacturers evaluating agentic AI on efficiency alone are measuring the wrong thing. The workforce constraint is the more urgent case, and it is not going away. With hundreds of thousands of jobs unfilled today and millions more coming, the manufacturers that use agentic AI to extend their scarce skilled workforce will out-operate the ones still trying to hire their way out of a structural shortage. The technology is the most credible lever available for the labor problem, but only when deployed to augment people rather than to chase a headcount reduction that the labor market has already made for you. If your manufacturing organization is planning agentic AI as a workforce strategy, connect with Advaiya’s team. With deep Microsoft AI and manufacturing experience, Advaiya helps US manufacturers deploy agentic AI that extends the reach of skilled workers, built on the integrated data foundation that augmentation requires. Frequently asked questions How does agentic AI help with the manufacturing labor shortage? Agentic AI extends the reach of a scarce skilled workforce rather than replacing workers, capturing expert knowledge before it retires out of the building, handling coordination work that consumes skilled time, and providing continuous monitoring a lean team cannot sustain, letting a smaller team operate at the level of a larger one. How bad is the US manufacturing labor shortage? The shortage is structural. Nearly 500,000 manufacturing jobs are currently unfilled, and by 2028 more than 2 million could go unfilled. The workforce skews older than the national average, and skill availability rather than raw headcount is now the dominant constraint as baby boomers retire and reshoring accelerates. Does agentic AI replace manufacturing
The first 90 days after a PPM migration: a post-cutover audit checklist
Migration completion gets mistaken for migration success, and the difference surfaces in the weeks after go-live: resource assignments that do not reconcile, reports that disagree with the old numbers, portfolio views that quietly drift from reality. The cause is rarely the migration itself, but the absence of structured validation after the cutover, the phase most teams skip because the data appeared to load fine. A disciplined post-cutover audit catches those defects while they are small, before they shape a quarter of decisions made on numbers nobody checked. The checks that matter most are not evenly spaced; they cluster in the first week, tighten through the first month, and formalize by day 90. Why the first 90 days decide migration success The first 90 days matter because migration defects do not announce themselves. Data loads successfully and the system goes live, yet within days integration errors, reconciliation gaps, and reporting mismatches begin to surface in live processes. Research compiled by the Bloor Group found that more than 80% of data migration projects run over time or over budget, with cost overruns averaging 30% and time overruns averaging 41%, and much of that damage traces to validation gaps that surface after go-live. Structured post-migration validation is what separates a controlled transition from a slow-motion problem. For PMO leaders and program sponsors, this window is not about technical confirmation. The real purpose is protecting operational continuity, financial integrity, and executive confidence in the new platform. A disciplined data migration approach treats validation as a defined phase, not an afterthought. Week 1: confirm nothing critical broke The first week is about catching the high-severity issues that disrupt daily work. Run these validations within the first days of go-live, not deferred to the following week. Run these validations immediately: Reconcile record counts between the source and the new system to confirm every project, task, and resource migrated Verify active projects open correctly with schedules, dependencies, and assignments intact Confirm user access and permissions match intended roles, with no excessive or missing authorizations Test that critical integrations, ERP, financial, and reporting connections are passing data correctly Check that in-flight approvals and workflows resumed in the new environment Integration errors often surface days after go-live, so early monitoring reduces exposure. Any critical defect found this week should be logged centrally, assigned an owner, and tracked to resolution rather than left to resolve itself. Connecting the new platform through disciplined business process automation helps confirm that automated workflows fire correctly. Weeks 2 to 4: validate data accuracy and reporting With the system stable, the focus shifts to confirming that the data is not just present but correct, and that it behaves properly inside live processes. Reconcile financials and resource allocations Confirm that project budgets, cost data, and resource allocations in the new system match the validated source figures. Multi-project consolidations should balance, and portfolio rollups should reconcile to the sum of their parts. Connecting this validation to trustworthy analytics and reporting ensures leadership sees numbers they can rely on. Verify reports match the old baseline Run the key portfolio and status reports in the new system and compare them against the reports the old platform produced for the same period. Discrepancies here erode executive trust fast, so any mismatch needs a documented explanation or a fix. Confirm complex transactions are reconstructed correctly Automated scripts verify record counts and totals, but manual review confirms that complex items, cross-project dependencies, cost-loaded schedules, and change orders are reconstructed correctly in the new environment. Days 30 to 90: Stabilize and formalize The final phase moves from firefighting to establishing steady-state operations and confirming the migration delivered what it promised. Establish a reconciliation cadence Set daily, weekly, and monthly validation cycles with clear pass-rate targets, then automate the checks where feasible. Validation should shift from reactive scrambling to a systematic rhythm embedded in governance. Building this into the work and operations management routine keeps data quality from drifting after the project team moves on. Keep the legacy system in read-only mode Retain the old platform in read-only mode for at least 90 days to support lookups and corrections that surface during normal business cycles. Decommissioning too early removes the reference point you need when a question arises about historical data. Document lessons learned While the experience is fresh, record which data issues caused the most remediation, which validation checks proved most valuable, and where timeline estimates missed. Capturing this improves the next migration and strengthens the enterprise architecture approach for future platform changes. Close out hypercare with a formal sign-off End the intensive support period with a documented review confirming that data is validated, reports reconcile, integrations are stable, and users are operating confidently. Formal sign-off marks the real finish line, not the cutover weekend. Treat go-live as the start, not the finish A PPM migration is not complete when the data loads. Completion comes when you have proven, through structured validation across the first 90 days, that the new platform holds accurate data, produces trustworthy reports, and supports the decisions your organization makes every day. The teams that treat the post-cutover window with discipline protect their credibility and their data. The ones that declare victory at go-live spend the next quarter discovering what they missed. If your organization is planning a PPM migration or wants to validate one already underway, connect with Advaiya’s team. As a OnePlan managed partner with deep migration and Microsoft expertise, Advaiya helps organizations execute structured migrations and post-cutover validation that turn go-live into a controlled, confident transition. Frequently asked questions What is a post-cutover audit in a PPM migration? A post-cutover audit is structured validation performed after a project portfolio management system goes live, confirming that migrated data is complete, accurate, and behaves correctly in live processes. The audit covers record reconciliation, financial and resource validation, report verification, and integration testing across the first 90 days. Why is the first 90 days after migration so important? Migration defects rarely appear immediately. Within days and weeks, reconciliation
The historical reporting risk nobody flags when migrating off Project Online
Most Project Online migration plans account for schedules, tasks, and resources. The item that quietly breaks, and rarely appears on the checklist, is the reporting layer. Project Online stores its data in SharePoint Online, while its successor Planner Premium stores data in Dataverse. That single architecture change is why every Power BI dashboard built on the ProjectData OData feed stops working after migration, and why re-pointing a connection string will not fix it. For PMO and BI leads, this is the risk with the longest tail. A board dashboard or a compliance report that has run reliably for years is tightly coupled to a data model that ceases to exist on September 30, 2026. The schedules migrate. The reports do not. Why reporting is the overlooked casualty of the migration Reporting breaks because it depends on a data model, not just a data set. Project Online dashboards read from OData feeds and OLAP cubes tied to the SharePoint-based ProjectData schema. When the underlying platform moves to Dataverse, that schema disappears, and anything built on top of it loses its source. The organizations most exposed are the ones with the most mature reporting. Enterprise PMOs commonly run 30 to 50 custom fields per project for governance metadata, feeding executive dashboards that leadership relies on monthly. The more sophisticated the reporting, the more work it takes to rebuild, because none of it survives the platform change on its own. Microsoft’s lifecycle documentation confirms the September 30, 2026 retirement and that data becomes inaccessible after that date, which is why protecting this layer requires the enterprise architecture and data integration discipline that treats reporting as a first-class migration workstream, not a downstream afterthought. What actually breaks, and what is recoverable Not every asset carries the same risk. Sorting them by recoverability is what separates a controlled migration from a scramble. Power BI dashboards and power automate flows Dashboards and flows are the highest-risk items because they are tightly coupled to the PWA data model and not recoverable in any meaningful sense. Dashboards must be re-pointed at the new platform’s API, and flows re-authored against new triggers. Budget three to ten days per dashboard depending on complexity, and inventory every report before assuming it can be rebuilt quickly. Rebuilding on a modern analytics and reporting foundation is often the better path than replicating the old dashboards field for field. Custom fields, formulas, and resource logic The painful losses look like configuration rather than data: enterprise custom fields with their lookup tables and formulas, resource cost rates refined over years, and the segmentation that reflects your actual reporting hierarchy. Institutional logic like this took months to build and does not export on its own, so it needs to be documented and rebuilt deliberately as part of a structured work and operations management transition. Timesheet history Timesheet records are recoverable via OData while the service is live, and they matter more than most teams expect. Finance often relies on them quietly for capitalization reporting, billing, and revenue recognition. Organizations subject to SOX or government contracting requirements need this history captured in a records management system before retirement. SharePoint document libraries Attachments, status reports, and project site content stored in SharePoint remain recoverable through standard export tools, and on a slightly longer timeline than the service itself. Even so, inventory which libraries must stay searchable after retirement and archive them into your target document store deliberately. How to protect your reporting before the deadline The teams that avoid a reporting gap treat it as a distinct workstream that starts early, not a task discovered during cutover. Begin by inventorying by dependency, not by product name. List every Power BI dataset, OData feed, Excel workbook, scheduled refresh, and downstream integration, then identify which ones feed the board deck or a compliance filing. A PWA admin knows what is configured, but only a business owner can say whether a given report drives a monthly executive decision. Get sign-off from the PMO director, IT, records manager, and integration owners on what must be preserved. Next, rebuild the critical reports first on the new platform, validating each against the numbers the old dashboard produced for the same period. Connecting the rebuild to disciplined data migration practices ensures the historical baseline transfers intact rather than resetting to zero on the new system. Protect the reports that drive your decisions The Project Online retirement will not announce which of your reports are about to break. The dashboards keep working right up until the platform is gone, which is exactly why the reporting risk is so easy to miss until it is too late to fix cleanly. The PMOs that come through this without a gap are the ones treating historical reporting as a migration priority now, while the source system is still live and the data is still exportable. If your organization is planning a move off Project Online, connect with Advaiya’s team. With deep Microsoft data platform expertise and OnePlan migration experience, Advaiya helps PMOs preserve their historical reporting, rebuild executive dashboards, and protect the governance data that leadership depends on before the deadline arrives. Frequently asked questions Why do Power BI reports break when migrating off Project Online? Project Online stores data in SharePoint Online, while its successor Planner Premium stores data in Dataverse. Power BI dashboards built on the Project Online OData feed depend on the SharePoint-based data model, which disappears in the migration. The reports cannot be fixed by changing a connection string and must be re-authored against the new platform’s API. What Project Online data is not recoverable after retirement? Power BI dashboards and Power Automate flows are not recoverable in any meaningful sense because they are tightly coupled to the PWA data model. Custom field formulas, refined resource cost rates, and reporting hierarchy logic also do not export on their own and must be documented and rebuilt deliberately. How long does it take to rebuild Power BI reports after migration? Rebuilding a Power BI dashboard typically
AI and automation in textile manufacturing: practical wins beyond the pilot stage
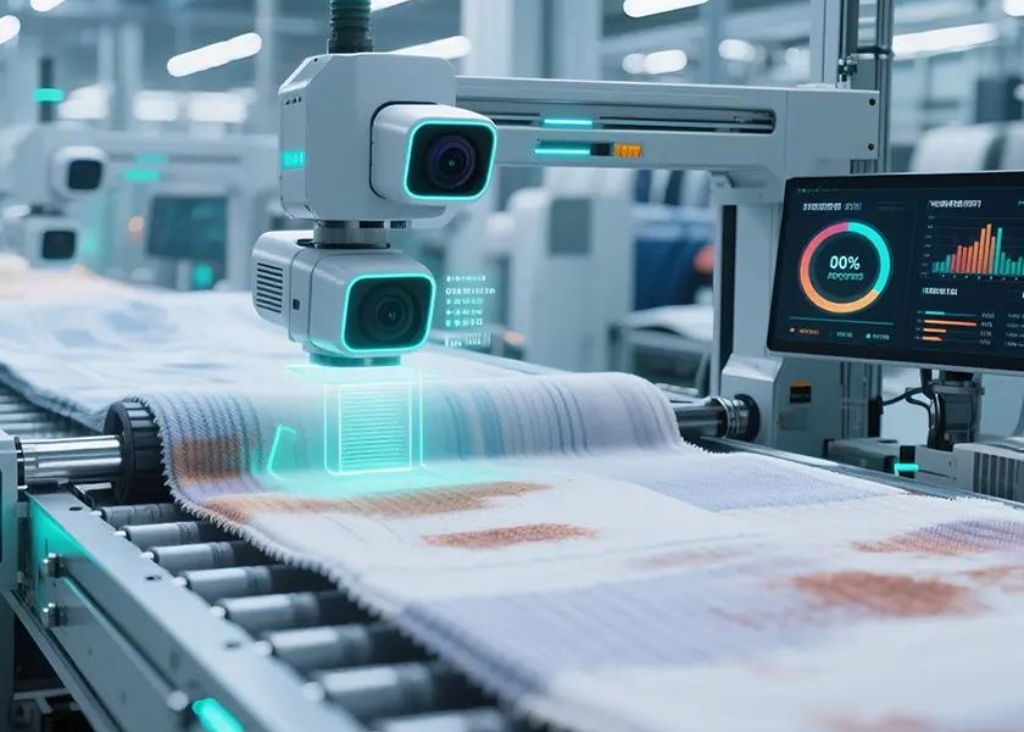
Most textile mills have run an AI pilot by now. Far fewer have moved one into full production, and the reason is rarely the technology. A pilot proves a model can spot a defect on a sample; production demands it grade every roll at full line speed, every shift, without an inspector babysitting the output. That gap is where most textile AI stalls. The wins that clear it share a pattern: they attach to a measurable cost the mill already tracks, and they hold up at production speed. Fabric defect detection is the clearest example, but it is not the only one. Here is where AI and automation are earning their place on the floor, and what separates a pilot from a mill-wide standard. Why textile AI stalls between pilot and production The pilot-to-production gap exists because the two prove different things. A pilot answers whether a model works on curated samples. Production asks whether it works on the messy reality of a running line, at speed, integrated with the systems the mill already uses. Manual fabric inspection runs at a limited table speed, and human accuracy degrades as fatigue sets in over a shift, so a defect that begins at high loom or knitting speeds can propagate through hundreds of meters before a person catches it. The AI systems that scale are the ones that close this specific gap, running at full production speed with consistent accuracy from the first roll of a shift to the last. Getting there depends on the enterprise architecture and data integration that connects the vision system to the mill’s existing quality and production data. Practical win 1: fabric defect detection at line speed Automated fabric inspection is the most production-ready AI application in textile manufacturing, and the one with the clearest financial case. Computer vision systems now scan fabric at full production speed with high defect detection accuracy, catching holes, broken yarns, weave inconsistencies, and shade deviations that manual inspection at line speed physically cannot match. Peer-reviewed research published by Springer Nature documented an AI-driven anomaly detection system reaching 97.13% accuracy using an ensemble of deep learning models, with system uptime above 99.7% across a three-month industrial trial. The economic logic is direct. Undetected surface defects can reduce a fabric roll’s resale value substantially, and a fault caught early prevents that loss from propagating across an entire roll. The proof points that turn a pilot into a mill-wide standard are concrete: the first weaving fault caught before it spread, the first shade mismatch flagged before shipping, the first automated grade generated without manual review. Connecting inspection data to AI-driven quality analytics is what turns individual catches into a system that improves over time. Practical win 2: predictive maintenance on critical machines Unplanned downtime on looms, knitting machines, and finishing lines is one of the most expensive disruptions a mill faces. Predictive maintenance uses sensor data and machine learning to flag developing failures before they stop production, shifting maintenance from reactive to planned. The win scales when it targets the machines where downtime hurts most rather than instrumenting everything at once. Starting with a few critical assets delivers results that justify expansion, the same phased logic that governs any successful business process automation program. Sensor data on vibration, temperature, and motor health feeds models that learn each machine’s normal signature and alert on deviation. Practical win 3: automated production reporting and analytics Many mills still compile production data manually, working from shift summaries and spreadsheets that are hours or days old. Automating this reporting connects looms and finishing lines to a central data platform, giving supervisors real-time visibility into output, downtime, scrap, and quality. Real-time reporting is not glamorous, but it is one of the fastest wins to deploy and the foundation everything else builds on. Connecting production equipment to a unified data infrastructure turns scattered machine data into the evidence base that supports defect detection, predictive maintenance, and better production decisions. What separates a scaled deployment from a stuck pilot The mills that move past pilots share three habits, regardless of which application they start with. They anchor each deployment to a cost the mill already measures, defect-related rework, downtime hours, or scrap rate, so the return is visible. They validate at full production speed and real conditions, not on curated samples in a lab. They integrate the AI with existing quality, production, and ERP systems rather than running it as a standalone tool that creates another data silo. Deployments that skip these steps produce impressive demos that never reach the floor. The ones that follow them turn a single proven line into a mill-wide standard. Move your textile AI from proof to production The textile mills pulling ahead are not the ones running the most pilots. The winners picked a win tied to a real cost, proved it at full line speed, and integrated it into how the floor already works. Fabric defect detection, predictive maintenance, and automated reporting are production-ready today, and the gap between a mill that scales them and one that keeps piloting shows up directly in rework, rejections, and downtime. If your textile operation is ready to move AI from pilot to production, connect with Advaiya’s manufacturing team. Advaiya combines Microsoft Azure, IoT, and AI expertise with the enterprise architecture approach that integrates AI into the quality, production, and ERP systems your mill already runs. Frequently asked questions What AI applications work best in textile manufacturing? The most production-ready applications are fabric defect detection using computer vision, predictive maintenance on critical machines like looms and finishing lines, and automated production reporting. Each attaches to a measurable cost the mill already tracks, which makes the return visible and the deployment easier to justify. How accurate is AI fabric defect detection? Peer-reviewed research documents AI fabric inspection systems reaching accuracy above 97% at full production speed using ensembles of deep learning models. Manual inspection accuracy, by contrast, degrades over a shift due to operator fatigue and the physical limits
Supply disruption alerts for discrete manufacturers: What AI can actually flag early
Every supply chain vendor now sells “AI-powered disruption prediction,” and the claims run well ahead of what the technology actually delivers. AI cannot tell you a port will close next Tuesday. What it can do, and this is genuinely useful, is detect the early signals that a disruption is forming while there is still time to act: a supplier’s on-time performance quietly slipping, a component’s lead time creeping up, a weather pattern building toward a key facility. For discrete manufacturers running on hundreds of components from dozens of suppliers, the value is not prediction in the crystal-ball sense. The real payoff is early warning, surfacing the weak signals a human team would miss until the shortage already hit the line. Knowing exactly what AI can and cannot flag is the difference between a useful investment and an expensive dashboard nobody trusts. What “early warning” actually means for supply chains Early warning means detecting the patterns and anomalies that precede a disruption, not forecasting the disruption itself. Machine learning analyzes shipment tracking, supplier performance, inventory levels, weather data, and news feeds to identify the signals that historically came before a problem. The distinction matters for setting expectations. According to EY research, 25% of supply chain leaders admit their organizations are unprepared for geopolitical tensions like wars or tariffs, and nearly a quarter lack readiness for transportation disruptions. AI does not eliminate these disruptions. What it does is shorten the gap between when a signal appears and when a human notices, which is where the data infrastructure connecting these data sources earns its return. What AI can genuinely flag early AI-driven supply chain monitoring is most reliable at detecting specific, data-rich signals. The four below are the alerts worth building a program around. Supplier performance degradation A supplier heading toward trouble usually shows it in the data before they announce it. Slipping on-time delivery rates, lengthening response times, and rising defect rates are all detectable patterns. AI monitoring supplier performance across your whole base can flag a deteriorating supplier weeks before the relationship becomes a shortage, supported by the business process automation that keeps supplier data current. Lead time creep on critical components Component lead times drift upward before they spike. AI tracking lead times across components and suppliers catches the gradual creep that manual review misses, giving procurement time to qualify alternate sources or adjust safety stock before the creep becomes a stockout. Demand and inventory anomalies Predictive models identify demand fluctuations and inventory patterns that signal a developing imbalance. Catching an unusual consumption pattern early lets a manufacturer adjust orders before a shortage or an overstock builds, connecting demand signals to the work and operations management systems that drive production planning. External event signals AI systems monitoring weather data, news feeds, and logistics reports can flag external events, a storm building toward a supplier region, a port congestion trend, that may affect inbound materials. The alert does not prevent the event, but it buys time to reroute or build buffer stock. What AI still cannot do Setting honest expectations is what keeps a disruption program credible. AI has real limits. AI cannot predict genuinely unprecedented events with no historical pattern to learn from, the true black swans. Bad data is a hard limit too, and supplier data in many manufacturers is incomplete or inconsistent, which directly caps prediction quality. The “black box” nature of some deep learning models can also make alerts hard to interpret, which is why explainability matters as much as accuracy for a team that has to act on the warning. Building on a solid enterprise architecture foundation is what addresses the data quality problem that undermines most disruption programs. How discrete manufacturers should start The manufacturers that get value from AI disruption alerts start narrow and build on data they already have. Begin with supplier performance monitoring, since the data already exists in your ERP and purchasing systems Focus first on your most critical components and single-source suppliers, where a disruption hurts most Prioritize alert explainability so the team trusts and acts on the warnings Integrate alerts into existing procurement workflows rather than creating a separate dashboard nobody checks Starting with the highest-risk components and the data already in hand produces early wins that justify expanding the program, the same phased logic that governs any successful analytics initiative. Turn weak signals into early moves The value of AI in supply chain disruption is not a crystal ball. The real return is the extra days or weeks of warning that let your team act before a supplier problem becomes a stopped line. Discrete manufacturers running on complex component networks have more weak signals in their data than any human team can track, and surfacing those signals early is exactly what AI does well. Setting honest expectations about what it can and cannot flag is what turns the investment into a capability your team actually trusts. If your organization is ready to build realistic supply chain early warning, connect with Advaiya’s team. Advaiya combines Microsoft Azure, AI, and data platform expertise with the enterprise architecture approach that unifies supplier, inventory, and external data into the early-warning signals discrete manufacturers need. Frequently asked questions What can AI actually predict in a supply chain? AI detects early signals that precede disruptions rather than forecasting the disruptions themselves, reliably flagging supplier performance degradation, lead time creep on components, demand and inventory anomalies, and external event signals from weather and news data, giving teams time to act before a problem reaches the production line. Can AI prevent supply chain disruptions? No. AI cannot prevent or eliminate disruptions. What it does is shorten the gap between when a warning signal appears in the data and when a human notices, providing early warning that lets teams reroute, qualify alternate suppliers, or build buffer stock before a disruption affects operations. What are the limits of AI in supply chain prediction? AI cannot predict genuinely unprecedented events with no historical pattern, cannot compensate for incomplete